Reading time: 12 min
The AI agent control loop is where whiteboard designs meet reality. On the board it is a box for the model, arrows for tools, a line back to the start. In production it is prompt drift on the third iteration, a tool call that silently returns garbage, and no stopping condition anywhere.
- 4
- Loop phases, and conflating two of them breaks validation
- 3
- Failure modes that account for most incidents
- 3
- Points where guardrails have to sit
- 2
- Monitoring tracks, offline and live
This article is about the engineering internals rather than the strategy. For scoping, framework selection and the wider lifecycle, our AI agent development process covers the regulated-environment view and how to build an AI agent covers the no-code against code-first fork. What follows is the part that decides whether any of it survives contact with production traffic.
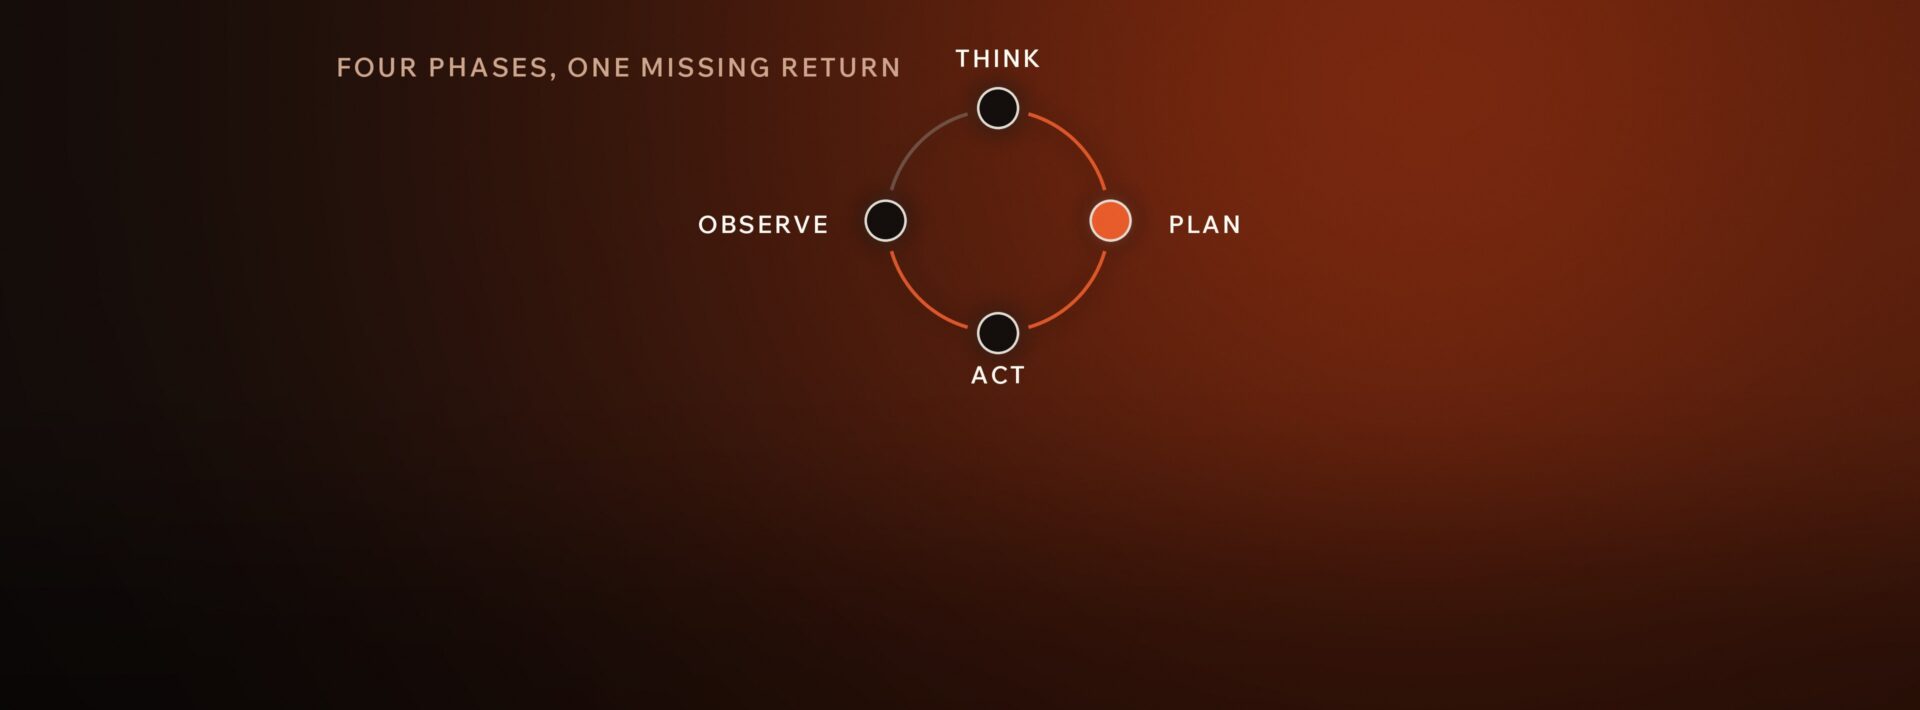
The AI agent control loop has four phases, not two
Think, plan, act, observe. The agent reasons over current task state, selects a tool and constructs the call, executes it, then updates context from what came back before looping again.
| Phase | Responsibility | What breaks without it |
|---|---|---|
| Think | Reason over task state | The agent acts on stale context |
| Plan | Select a tool, construct the call | Malformed calls execute unvalidated |
| Act | Execute the chosen action | Nothing happens, or the wrong thing does |
| Observe | Update context from the result | The loop repeats a failed step forever |
Swipe the table sideways to see all columns.
That merge is the single most common shortcut, usually made for latency, and it is the one that turns a recoverable error into a silent corruption. Keeping the phases separate costs a few hundred milliseconds and buys you a validation point.
ReAct and Reflexion: two ways to run the loop
ReAct is the practical implementation for tool-heavy workflows. It interleaves reasoning traces with action calls, so the decision path stays inspectable at every step rather than only at the end. When something goes wrong you can read what the agent believed at the moment it chose badly, which is the difference between a debuggable system and a guess.
Reflexion extends the same cycle with a reflect phase after observation, using external evaluation signals to refine strategy before the next iteration. It costs tokens and latency, so it earns its place on tasks where the agent gets more than one attempt and quality matters more than speed. On single-shot tasks it is overhead.
Ask whether a wrong answer is recoverable within the same session. If the agent can try again and be measured on the second attempt, Reflexion pays for itself. If the first action is irreversible, a payment, a deletion, an outbound message, no amount of reflection helps and the effort belongs in the guardrail layer instead.
Three AI agent control loop failure modes and their fixes
- Tool misuse with wrong argumentsThe agent constructs a plausible-looking but invalid call. Fix: register every tool with a strict argument schema and configure it to reject unknown fields outright. Rejection at the boundary beats a tool that accepts nonsense and returns something shaped like success.
- Infinite loops from missing stopping conditionsFix: a hard iteration cap, plus no-progress detection that compares state between cycles and halts when nothing changed. The cap alone is not enough, because an agent can burn every iteration making the same failed call.
- Context loss across long tasksFix: keep state in an external store rather than in-context memory alone, and add checkpoint support so a long-running agent resumes across sessions without losing the task. In-context state is a cache, not a database.
All three trace back to the same root: a loop written to work on the happy path, with no explicit answer to what happens when a step fails. Treat iteration caps, no-progress detection and a token budget as required rather than as hardening you add later.
Tool integration and state around the AI agent control loop
Strict schemas are the cheapest reliability win available. A tool that rejects unknown fields prevents an entire class of runtime error where the agent invents a parameter, the tool ignores it, and every subsequent step reasons over a result that answered a different question.
Two data-layer practices matter as much as the schemas, and both belong in the plumbing rather than in a review checklist.
- Mask PII where data is passed, not after. Sensitive fields should be masked or redacted at the schema level before anything moves between components or out to an external tool. Retrofitting this means auditing every call path you already built.
- Treat every retrieved document as untrusted. Strip instruction-like text from retrieved content and tag chunks with provenance metadata, so downstream policy checks know where a claim came from before acting on it.
The provenance point is easy to skip and expensive to add later. A policy layer that cannot tell whether text came from your knowledge base or from a user-uploaded PDF cannot make a meaningful decision about it.
Guardrails sit at three points, not one
Safety is not a filter on the output. It is three separate responsibilities at three separate moments in the loop.
| When | Controls |
|---|---|
| Before the agent sees input | Input sanitisation, prompt injection detection via a lightweight classifier, intent classification against the user's role |
| During planning | Policy-as-code validation of the proposed action against business rules and access controls |
| After execution | Output filtering, factual verification against retrieved context, structured audit logging with correlation IDs |
The middle row is the one teams skip, and it is where the two-step commit pattern lives: the agent proposes an action, a separate validation layer approves or rejects it, and only approved actions execute. Approval logic sits outside the model, which is the whole point. A model asked to police itself is a single point of failure wearing two hats.
High-stakes actions need a human gate rather than autonomous execution: payments, deletions, anything that shares data externally. Encode that threshold in the policy layer rather than leaving the model to judge case by case. Those review checkpoints also generate the labelled feedback that improves the agent later, so the gate is not pure cost.
Output accuracy. Hallucination rate. False positive rate on blocked actions, which tells you whether the guardrails are strangling legitimate work. And audit coverage, meaning the share of agent actions with a complete trail. That last one is the one auditors ask for, and it is either instrumented from the start or reconstructed painfully.
For agents operating in the EU, the EU AI Act framework shapes what documentation and oversight obligations apply, which is worth reading against your own risk classification before you finalise the guardrail design.
Deploying and monitoring an AI agent control loop
The deployment path is unremarkable, which is the point: infrastructure as code for reproducible environments, CI/CD for repeatable releases, containerised runtime for portability, and full sandbox testing before any live traffic arrives. Managed options exist if you would rather not run this layer yourself, though platform capabilities in this space move quickly enough to be worth confirming with the provider rather than with an article.
Monitoring runs on two tracks, and both are necessary.
- Offline evaluation runs the agent across a curated scenario set before every release, catching regressions before users do. This is your test suite, and an agent without one ships on hope.
- Online monitoring watches live traffic for policy violations, output quality degradation and behavioural anomalies: unexpected tool call patterns, latency spikes, iteration counts creeping up.
One connection is worth making explicit. If the objective you wrote at the start was specific enough to be measured, the monitoring metrics map straight back to it, and monitoring becomes a feedback loop rather than an alarm. If they do not map, the objective was too vague, and that is a phase-one problem surfacing in phase five.
Frequently Asked Questions
What is an AI agent control loop?
What are the most common control loop failures in production agents?
What is the difference between ReAct and Reflexion?
Where should guardrails sit in an agent architecture?
When should a human approve an agent action instead of letting it execute?
Build the loop properly and the rest follows
Most agents that fail in production do not fail on model quality. They fail on a loop with no stopping condition, a tool that accepted an invalid argument, or a guardrail that only checked the output. None of those are hard problems. They are just the ones that get postponed because the happy path already demos well.
Start with one workflow that has clear inputs, defined outputs and a measurable success criterion. Get the four phases separated, the schemas strict, the state external and the guardrails at all three points.
A single agent built that way is the fastest route to a multi-agent system, because every lesson carries forward intact. On the instruction and tool-schema side, our piece on best practices for AI agent creation covers what cannot be retrofitted, and for the specialist-sourcing question, AI in IT outsourcing.
Book a call and we'll bring in specialists exactly where your gap is: architecture, control loop, guardrails or deployment.
Book a consultation